Auditing 22 Days of an Overnight Coding-Agent Loop
I designed a loop that hands overnight work to AI coding agents. Over 22 days it produced 56 pull requests.
This is not a write-up of that run. It is an audit of it, done afterwards against the records. It is organised around what the records did and did not contain, which constraints could be designed in advance and which were learned only by failing, and what the numbers actually were.
TL;DR
- The Loop Engineering framing, slightly extended
- 72 tickets → 56 PRs
- What stalled was the ticket, not the code
- Learned constraints need a shared home
- Don't let the loop trust claims or evidence
- Records cannot be backfilled, only started
Context
In early June 2026, I read a field guide on "Loop Engineering": an "Orange Book" by HuaShu documenting a term that surfaced that month from converging posts by Peter Steinberger, Boris Cherny, and Addy Osmani, and named in writing by Osmani. I decided to build one.
At that time, my company, a music software company, already had a loop to triage tickets, but we didn't have a loop to handle new features yet. Luckily, I had a new project re-implementing one of our existing apps on a second platform. I had already finished its detailed design, including writing up PoCs, ADRs and Linear tickets. The deadline was tight, so I decided to write a loop for it as a Claude Code skill.
To start small, I started the loop on my local MacBook Pro. I let the loop work on specific milestones, and while the loop ran I worked on the later, harder milestones that required heavy human intervention to maximize the efficiency. Later, other members started using the loop. Their runs are excluded from every number here.
0. Target: attended loop
The loop is attended. A human performs the final verification.
In the Loop Engineering framing, a turn consists of five movements (discovery, handoff, verification, persistence, scheduling), with human review alongside them. By making human review permanent, we can keep the loop trustworthy.
I take the same position. Where this document says "loop," it means an attended loop: autonomous execution with a human as the final gate.
1. What I built
The workflow of the loop is as follows:
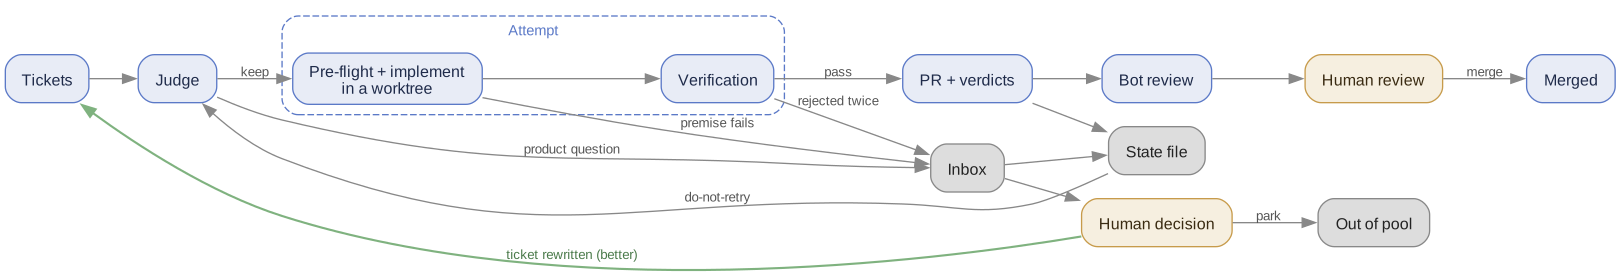
| Movement | Implementation |
|---|---|
| Discovery | Pull up to N ready tickets from the issue tracker |
| Judge | My addition to the Loop Engineering framing. Checks whether a ticket is ready or not. If it's not ready the ticket goes to the inbox without an attempt. |
| Attempt | Loop Engineering's handoff, broadened. After a ticket passes the Judge, handoff into an isolated worktree, a quick pre-flight check that re-checks the ticket's claims, implementation, verification, and persistence of the result. |
| Verification | An adversarial reviewer that is a separate agent from the implementer, plus two domain-specific checks |
| Persistence | State file / inbox note / PR |
| Scheduling | Local cron |
| Human review | Final verification by me. A human merges. |
Judge
The Judge checks a ticket's readiness on four points:
- The ticket is agent-codeable
- The spec is clear
- The ticket's claims check out
- The ticket's dependencies are met
Verification
Verification runs in three layers:
- Adversarial reviewer (general) — a separate agent reviews every implementer's diff (e.g., at parallelism four, four implementers and four reviewers run).
- UI check (domain-specific) — diffs against the reference implementation, the original app.
- Audio check (domain-specific) — runs only when the audio path is touched.
Persistence
- State file: a document storing settings, each
Attempt's result, and notes on findings and decisions. - Inbox note: a note written when the loop works on a ticket but the ticket needs to be escalated and requires a human decision. 1 note = 1 decision request, so one ticket can generate multiple notes. Inbox notes can be generated by
Judge,Attempt(Pre-flight + implement in a worktree), andVerification.
A CI and an external code-review bot also run on every PR.
LLM models
- Orchestration runs on Opus
- Implementers run on Sonnet with tightly scoped briefs
- The adversarial reviewer runs on Opus as a subagent, deliberately a different, stronger model than the implementers.
Note that the whole thing rides a flat-rate subscription; per-run token cost was not measured.
Directory structure
repo/
├── .agents/skills/night-loop/      ← tracked — the governing text (shared)
│   ├── SKILL.md                       the loop's instructions
│   ├── README.md                      operator's guide (human procedure)
│   ├── ops-lessons.md                 promoted traps (exists since the audit)
│   ├── attest.sh                      attribution check
│   └── report.sh                      morning digest
│
└── .workplace/night-loop/          ← untracked — one operator's state
    ├── state.md                       settings + attempt results + notes
    ├── inbox/                         hand-off notes, one decision each
    └── cron/
        ├── run-night-loop.sh          launch wrapper
        └── logs/run-*.log             keeps last 30 — then gone (§7)
1.5. How the loop evolved
| No. | Learning => Evolution |
|---|---|
| 1 | First version: one ticket a night. After I confirmed the loop succeeded, I increased the parallelism gradually => In the end, 10 tickets in parallel per night |
| 2 | Nothing proved which PRs were the loop's => add Git trailers + validation script |
| 3 | Learned pitfalls are stored only on local => store and track them as ops-lessons.md |
| 4 | "The claim outran its evidence" recurs across layers => Update the skill to enforce the validation |
| 5 | The loop will get more complex => Set up documents and tools for the human, for a better audit |
Note that operational failures did not shrink the loop's autonomy. Instead each one became a new constraint. Most nights ran below the 10-ticket cap; ready tickets were the limiter.
2. Measured results (22 days)
July 11 – August 1
Discovery
| Metric | Value |
|---|---|
| Tickets pulled by discovery | 72 |
Judge
| Metric | Value |
|---|---|
| Tickets judged and passed | 65 |
| Judged out at the gate - never attempted | 7 |
| Inbox notes written | 10 |
Attempt
| Metric | Value |
|---|---|
| Attempts | 66 |
| Tickets attempted | 65 |
| PRs produced | 56 |
| Merged | 54 |
| Closed unmerged | 0 |
| Reverted | 0 (none as of two weeks after the last merge) |
| Inbox notes written | 12 |
| PRs that later took a human commit | 2 / 56 (3.6%) — commits only; quiet steering was not recorded (§7), so a lower bound |
NOTE: There's 1 inbox note whose stage can no longer be determined
56 of 66 attempts (85%) produced PRs successfully. It's also good to note that the loop generated a total of 23 inbox notes that require human decisions (see §3).
The ledger, reconciled:
- 66 attempts on 65 tickets
- one ticket was attempted twice after its premise failed
- 56 produced a PR, 10 did not
- 6 escalated and stopped during implementation or verification (see §3)
- 3 found already done (1 of these left an inbox note)
- 1 ticket needed splitting
- 56 PRs merge state
- 54 merged at the audit date
- 2 open, both merged two days later
- 0 closed unmerged
- The 10 (Judge) + 12 (Attempt) + 1 (uncertain) = 23 inbox notes
- Notes are per-decision, not per-ticket
- They trace to 19–20 tickets, one of which produced three notes
- Every number comes from one operator's ledger on one machine
Scale of the work
The PRs were not trivial: across the 49 measured PRs, median 397 lines and median 3 files per PR, ~24.7k lines in total (size distribution in the appendix).
Character of the tickets: scoped features and fixes in one TypeScript sub-app built around a real-time audio engine.
3. Finding 1 — What stalled was the ticket, not the code
Now let's take a closer look at the Inbox notes.
Places where the Inbox note was produced
23 notes:
|- 10  <- Ended at Judge and never attempted, from 7 tickets
|- 2   <- Attempted but ended at the pre-flight check, before implementation, from 2 tickets
|- 6   <- Attempted and passed the pre-flight check but ended during implementation or verification, from 6 tickets
|- 4   <- Attempted and produced a PR, and also left a note, from 4 tickets
|- 1   <- Attribution uncertain — its file was modified after the audit date
In total 7 + 2 + 6 + 4 = 19 (possibly 20, counting the uncertain note) of the 72 tickets the loop pulled (~26%) left at least one note.
Classifying the 23 notes that landed in the inbox
| Kind No. | Kind | Count |
|---|---|---|
| 1 | The ticket's premise was wrong — reading the code showed the acceptance criteria could not hold | 7 |
| 2 | No counterpart in the reference implementation; needs a product decision | 7 |
| 3 | Rejected twice by the loop verification within a single attempt, then abandoned | 4 |
| 4 | Specification too thin, or needs splitting | 4 |
| 5 | Already implemented | 1 |
NOTE:
- Kind No. 2: all 7 inbox notes were generated by the lack of a product spec. For example, one ticket described a future feature whose system design was not finished yet.
Kinds 1, 2 and 4 (18 of the 23 notes) put the stall in the ticket itself. Kind 3 (4 notes) puts the stall in the code. Ticket failures outnumber code failures 4.5 to 1. Among the stalls, the ceiling was set by specification quality, not by the agent's ability to implement (defects that survived into merged PRs are invisible to this classification, see §7).
The Orange Book argues that "discovery sets the ceiling on the whole loop's quality." I have not found a published number for where that ceiling actually sits. In this environment: 18 of the 23 stalls, and four and a half times the code's own failure contribution.
If we do not write tickets well, the shortfall accumulates in the inbox instead of in the code.
How I ended up handling those tickets:
- Kinds No. 1, 2 and 4: decisions were made later by me by checking the inbox notes.
- Kind No. 3: I resolved them by reimplementing myself, or by reevaluating and reshaping the ticket. It means that even in some of the agent's code failures, I found pitfalls of the spec.
A reshaped ticket can re-enter the loop: one stalled ticket came back with its premise fixed and merged on the second attempt.
4. Finding 2 — Constraints split into the designable and the learnable
As with any Claude Code skill, I set up constraints to run a better loop. Through many failures while running it, I kept finding new constraints worth adding. In total the loop has 38 constraints.
I classified all 38 constraints imposed on the loop by where they came from.
| Origin | Count | Share |
|---|---|---|
| Designed up front | 13 | 34% |
| Added afterwards | 18 | 47% |
| Added when expanding autonomy | 6 | 16% |
| Origin unknown | 1 | — |
Examples:
- Designed up front: never merge, never push to main / two attempts per ticket, then stop / payments, auth, migrations, infra are out of scope.
- Learned by failing: run the whole test lane instead of a single test file (execution platform) / only one reference source may answer layout questions (domain) / the formatter prints "success" while exiting non-zero (tooling defect).
47% added afterwards sounds like weak up-front design. The breakdown reverses that reading.
- All 13 designed up front concern what the agent may do — domain boundaries, permission boundaries, limits, stop conditions.
- Not one of the 18 pure additions is about what the agent may do. Every one concerns what silently breaks around the loop:
- execution platform (6 — what the loop runs on: agent runtime, cron, worktrees)
- dev environment-specific (4 — only on my machine)
- domain (5)
- buggy tools (3 — they report wrong results)
- The 6 "added when expanding autonomy" were the price of giving the loop more room: a higher parallelism cap, or a new milestone in scope.
Boundaries can be designed. Traps have to be learned.
In addition to that, 14 of those 18 learned constraints existed only in local files outside version control. Almost everything the loop learned lived on a single machine. For the domain-specific constraints, I ended up updating the skill to store and track them in a single markdown file (ops-lessons.md).
5. Finding 3 — Nothing was checking the evidence
During the Verification phase, the sub-agent reviewers assess the work. But the evidence they assess it by (screenshots, test output, diffs) was itself unchecked. When the evidence was wrong, nothing noticed. For example, we faced the following issues:
- A verification harness that reported MATCH while the bug was fully present
- A formatter that printed success while exiting non-zero
So a layer was added that asks one question before any verdict counts: does this evidence actually correspond to this change? It checks hashes and freshness. Verification is only as good as the evidence it stands on.
6. Finding 4 — "The claim outran its evidence" recurs across layers
The most important thing the audit found is that the same failure was happening independently at two different layers.
| Layer | What's wrong |
|---|---|
| Judge | ticket claims taken as facts |
| Verification | evidence taken as real |
Examples:
- At the Judge — a ticket saying "X is broken, reproduce at width Y". In one case the phenomenon was real but the written reproduction was wrong. The loop's implementation chased the wrong condition.
- At Verification — the §5 failures above
I faced the same failure case outside of the loop, months before it existed. A dozen tickets on our error-tracking board had been closed in bulk, and I asked an agent to investigate it. It cited a rule, concluded a violation, drafted a detailed ticket. It was actually not automation. The ticket log showed who (a colleague), and when I asked, they confirmed they had cleaned up the board by hand. The colleague had done nothing wrong, my question had. My question carried the premise, and a question containing a premise returns findings that support that premise.
In the end, I updated the skill to verify inputs wherever an agent receives them. The rule has a name: inputs are claims, not facts. It applies to the operator's questions too.
7. What was not recorded
The record-design problems the audit exposed, listed as they are.
| Missing records | Detail | Remediation |
|---|---|---|
| Loop's authorship | Written only in the PR body, which can be edited or overwritten at any time | Add Git trailers + validation script |
| Learned constraints lived on one machine | 14 of 18 learned constraints in untracked local files | The 5 domain-specific ones now tracked in ops-lessons.md; the rest remain local |
| The proof of human intervention | It's ambiguous whether "the loop did this" or "the loop did this with a human quietly steering" | Store human intervention log |
| Run logs rotate away | logs/run-*.log keeps only the last 30 runs — older runs are destroyed |
Morning digest on Slack preserves a per-run summary |
| Execution records lived on one machine | All 66 attempt rows in an untracked state file | TODO |
| Bugs after merge | A bug in merged work becomes a new ticket or a follow-up PR, but nothing links it back to the original PR | TODO |
| The adversarial reviewer's feedback | Also lived only in the PR body — same weakness as the loop's authorship | TODO |
| Token cost for each run | The whole thing rides a flat-rate subscription, but it should be tracked for efficiency | TODO |
| Inbox notes decay | Notes are deleted when the human processes them, and rewritten when a later run revisits the ticket — attribution became unrecoverable for 1 of 23 within weeks | TODO |
8. Summary
- Among the stalls, the ceiling was set by specification quality, not the agent's ability. Ticket failures outnumbered code failures; the agent was the bottleneck in at most 4 stalls of 23.
- Boundaries can be designed; traps must be learned. Learned traps must have somewhere shared to go.
- You need a layer that distrusts the evidence itself.
- "The claim outran its evidence" showed up everywhere: it hit the ticket claims, the evidence, and the operator's own questions. We need to check it at every door.
- The loop destroys its own audit trail. Record design can only be installed at the start. We need to decide up front what we will later want to prove.
The loop still runs every night. The audit is now part of it. The tools that made this audit possible: the attribution check, the digest, the shared home for learned constraints. They are still specific to this one loop. As a next step, I'll try to generalize them so any loop can answer the same questions.
Appendix: scale of the work
| Metric | Value |
|---|---|
| Lines changed per PR | median 397 / p75 602 / p90 1,110 / range 42–2,087 |
| Files touched per PR | median 3 / p90 11 / max 17 |
| Size buckets | ≤100 lines: 2 · 101–500: 30 · 501–2,000: 16 · >2,000: 1 |
| Total | ~24.7k lines across 49 merged PRs in 22 days |
The table covers the 49 PRs whose URLs the ledger recorded in-row; the other 7 were matched afterwards from leftover PR-body files, after these statistics were computed, so their sizes are not included. All 56 are merged as of writing.
References
- HuaShu, Loop Engineering: The Orange Book (v260615, June 2026) — https://github.com/alchaincyf/loop-engineering-orange-book
- Addy Osmani, "Loop Engineering" (the founding post) — https://addyosmani.com/blog/loop-engineering/
- Peter Steinberger on X, June 2026 — https://x.com/steipete/status/2063697162748260627
- Boris Cherny on X, June 2026 (self-verification loops) — https://x.com/bcherny/status/2064426115255730578